Calculate Completeness (Sample Coverage) Over Space or Time
Source:R/indicator_wrappers.R
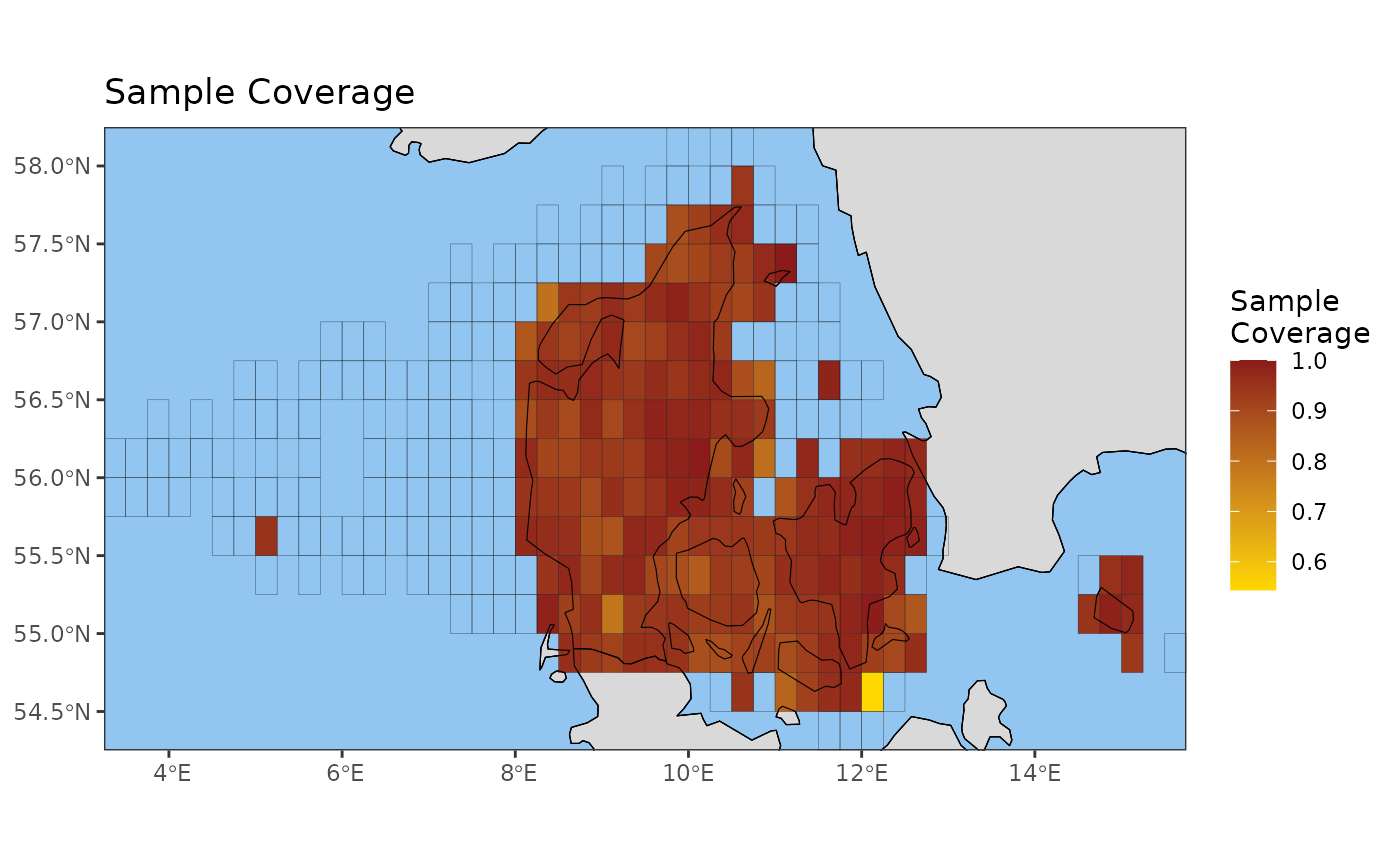
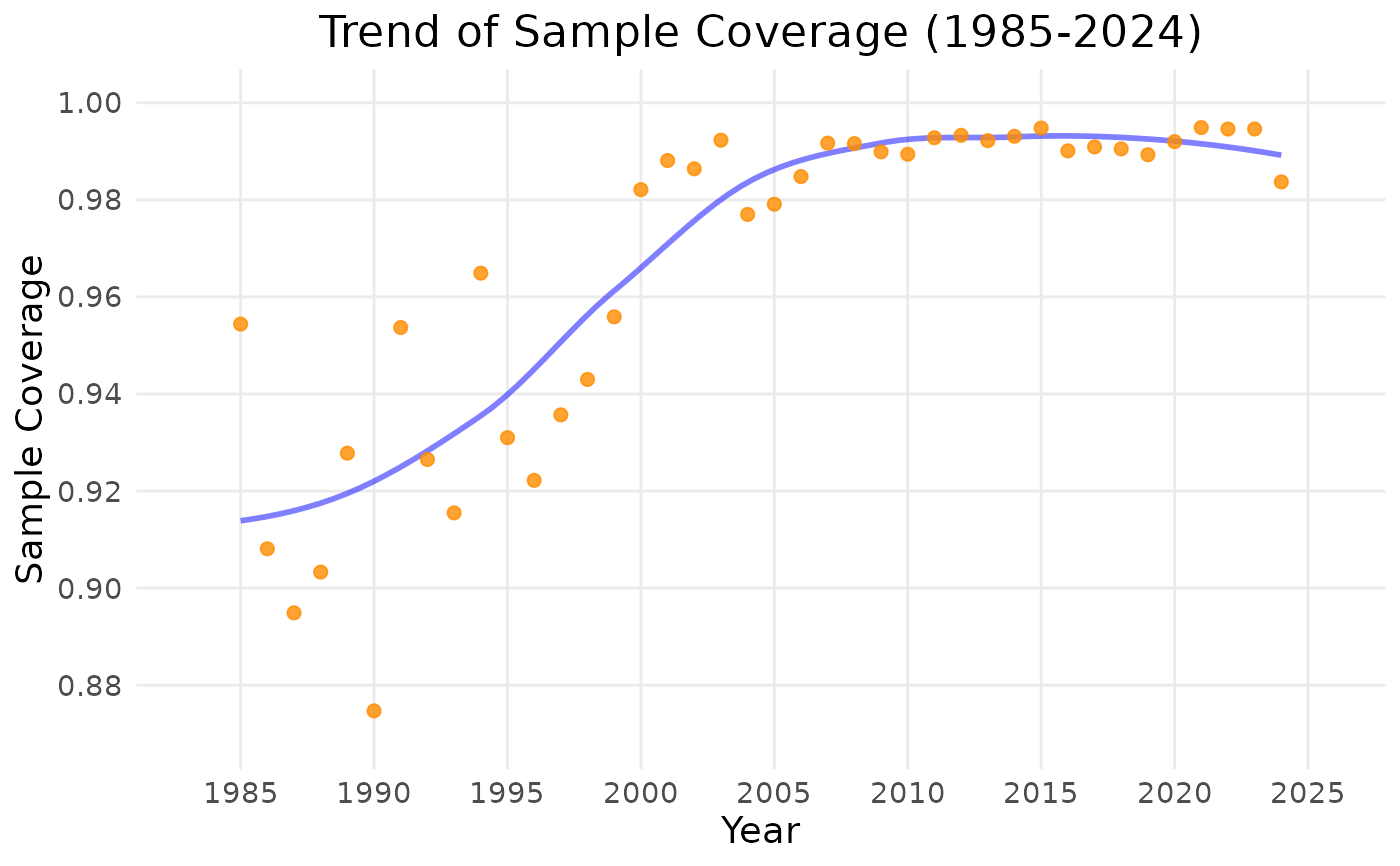
completeness_map.RdThis function calculates the completeness of biodiversity data over a gridded map or as a time series using the Sample Coverage metric from the iNEXT package.
Usage
completeness_map(
  data,
  cutoff_length = 5,
  data_type = c("incidence", "abundance"),
  assume_freq = FALSE,
  ...
)

completeness_ts(data, cutoff_length = 5, gridded_average = FALSE, ...)
Arguments
- data
A data cube object (class 'processed_cube').
- cutoff_length
(Optional) Minimum amount of data required for a grid cell or year to be included. For maps, grid cells with fewer than
cutoff_lengthspecies are removed. For time series, years whose species-by-cell incidence matrix hascutoff_lengthentries or fewer are removed (withgridded_average = TRUE: coarse grid cells containingcutoff_lengthor fewer native cells with records that year). Default is 5.- data_type
(Optional, maps only) The type of data: "incidence" or "abundance". Default is "incidence".
- assume_freq
(Optional, maps only) Whether to assume frequency data if using incidence. Default is FALSE.
- ...
Arguments passed on to
compute_indicator_workflowcell_size(Optional) Length of grid cell sides, in km or degrees. Only used for maps and for time series that require a grid.
"grid"(default): use the native resolution of the cube. If this would produce more than about 1 million grid cells over the study area (for degree-based cubes: if the resolution is finer than 1 degree for 'world' or 'continent', or finer than 0.1 degrees otherwise), you are asked to confirm in an interactive session, and the function stops with an error in a non-interactive session."auto": determined automatically. For km-based grids it depends on the area of the study region: 100 km for areas of at least 1 million sq km, 10 km for at least 10,000 sq km, 1 km for at least 100 sq km, and 0.1 km for smaller areas. For degree-based grids it is 1 degree for 'world' or 'continent' and 0.1 degrees otherwise. The automatic size is never smaller than the cube's resolution.A number (in the units of the cube's resolution, i.e. km or degrees), or for km-based grids a string such as
"10km"or"500m".
A manually selected cell size must be a whole number multiple of the cube's resolution.
level(Optional) Spatial level: 'cube', 'continent', 'country', 'world', 'sovereignty', or 'geounit'. (Default: 'cube')
region(Optional) The region of interest (e.g., "Denmark"). Ignored if level is 'cube' or 'world'. (Default: "Europe")
ne_type(Optional) The type of Natural Earth data to download: 'countries', 'map_units', 'sovereignty', or 'tiny_countries'. This parameter is ignored if level is set to 'cube' or 'world'. (Default: "countries")
ne_scale(Optional) The scale of Natural Earth data to download: 'small' - 110m, 'medium' - 50m, or 'large' - 10m. (Default: "medium")
output_crs(Optional) The CRS you want for your calculated indicator. (Leave blank to let the function choose a default based on grid reference system.)
first_year(Optional) Exclude data before this year. (Uses all data in the cube by default.)
last_year(Optional) Exclude data after this year. (Uses all data in the cube by default.)
spherical_geometry(Optional) If set to FALSE, will temporarily disable spherical geometry while the function runs. Should only be used to solve specific issues. (Default is TRUE).
make_valid(Optional) Calls st_make_valid() from the sf package after creating the grid. Increases processing time but may help if you are getting polygon errors. (Default is FALSE).
shapefile_path(optional) Path of an external shapefile to merge into the workflow. For example, if you want to calculate your indicator for particular features such as protected areas or wetlands.
shapefile_crs(Optional) CRS of a .wkt shapefile. If your shapefile is .wkt and you do NOT use this parameter, the CRS will be assumed to be EPSG:4326 and the coordinates will be read in as lat/long. If your shape is NOT a .wkt the CRS will be determined automatically.
invert(optional) Calculate an indicator over the inverse of the shapefile (e.g. if you have a protected areas shapefile this would calculate an indicator over all non protected areas within your cube). Default is FALSE.
include_land(Optional) Include occurrences which fall within the land area. Default is TRUE. Note that this is purely a geographic filter, and does not filter based on whether the occurrence is actually terrestrial. Grid cells which fall partially on land and partially on ocean will be included even if include_land is FALSE. To exclude terrestrial and/or freshwater taxa, you must manually filter your data cube before calculating your indicator.
include_ocean(Optional) Include occurrences which fall outside the land area. Default is TRUE. Set as "buffered_coast" to include a set buffer size around the land area rather than the entire ocean area. Note that this is purely a geographic filter, and does not filter based on whether the occurrence is actually marine. Grid cells which fall partially on land and partially on ocean will be included even if include_ocean is FALSE. To exclude marine taxa, you must manually filter your data cube before calculating your indicator.
buffer_dist_km(Optional) The distance to buffer around the land if include_ocean is set to "buffered_coast". Default is 50 km.
force_grid(Optional) Forces the calculation of a grid even if this would not normally be part of the pipeline, i.e. for time series. A grid is needed for time series of area-based rarity, Hill diversity and relative occupancy (and for completeness with
gridded_average = TRUE). This is switched on automatically for these indicators: the wrappersarea_rarity_ts(),hill0_ts(),hill1_ts()andhill2_ts()already setforce_grid = TRUE, so do not pass it to them. (Default: FALSE)
- gridded_average
(Optional, time series only) If TRUE, completeness is calculated separately for each cell of a grid coarser than the cube (using the native cube cells within it as sampling units), and the yearly value is the mean over these grid cells, rather than calculating it for the entire area at once. If
cell_sizeis left at its default ("grid"), a grid 4 times coarser than the cube's resolution is used; otherwisecell_sizemust be coarser than the cube's resolution. Default is FALSE.
Value
An S3 object with the classes 'indicator_map' or 'indicator_ts' and 'completeness' containing the calculated indicator values and metadata.
Details
Completeness (Sample Coverage)
Completeness is measured as Sample Coverage, a concept developed by Good (1953), crediting Turing, and further popularized in ecology by Chao and Jost (2012). Sample coverage estimates the proportion of the total individuals in an ecological community that belong to the species detected in a sample.
A coverage value of 1.0 indicates that no new species are expected to be uncovered through further sampling, meaning the sample is perfectly complete. A value of 0.8, for example, suggests that 20% of the individuals in the community belong to species that have not yet been detected in the sample.
Calculating sample coverage is a prerequisite for reliable comparisons of biodiversity across different areas or time periods, as it provides a standardized measure of sample completeness that is independent of sample size alone (Chao et al., 2014).
In this package, completeness is calculated using the 'iNEXT' package based on the observed data in each grid cell or time point. For time series, occurrences are converted to incidence data with the native grid cells of the cube as sampling units. For maps, see data_type and assume_freq (by default, years are the sampling units).
References
Good, I. J. (1953). The population frequencies of species and the estimation of population parameters. Biometrika, 40(3-4), 237-264.
Chao, A., & Jost, L. (2012). Coverage-based rarefaction and extrapolation: standardizing samples by completeness rather than size. Ecology, 93(12), 2533-2547.
Chao, A., Gotelli, N. J., Hsieh, T. C., Sander, E. L., Ma, K. H., Colwell, R. K., & Ellison, A. M. (2014). Rarefaction and extrapolation with Hill numbers: a framework for sampling and estimation in species diversity studies. Ecological monographs, 84(1), 45-67.